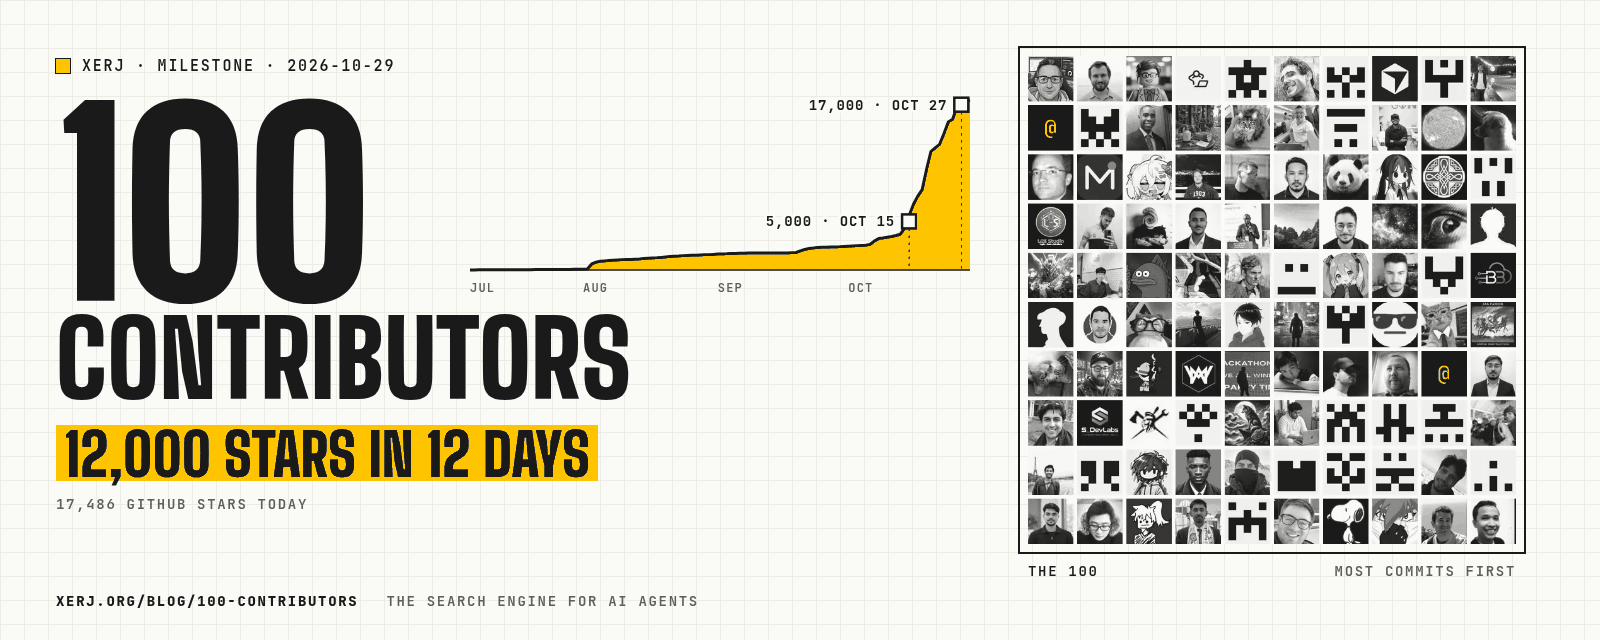
100 CONTRIBUTORS BEHIND
12,000 STARS IN 12 DAYS.
100 contributors build XERJ with us. In 12 days, from October 15 to October 26, their work earned 12,434 GitHub stars.
They sent fixes, features, tests, Corpus Hub corpora and honest field reports. Today XERJ has 17,486 stars, and it is the #1 Rust repository of the day and week on Trendshift. Thank you. You built this with us.
The 100 behind XERJ
We merged the first pull request from outside the core team on July 23. Since then, we have merged 342 pull requests from 96 outside contributors. 75 of them add a name to the contributor list. The other 267 changed XERJ:
- 44 field reports from 39 people. They ran XERJ on real work on Windows, macOS and Linux, and told us what worked and what broke. Those reports also made autoindex faster. One used
xerj codeas a retriever on SWE-bench Lite (#1187). - New file types for autoindex. PowerPoint, EPUB and man pages (#1117, #1159, #1134), Clojure and Scheme (#1305), PHP enums (#286) and system logs (#1508).
- New tools for agents. Go to definition and batch retrieval over MCP (#2166, #2333), and a list of agent memory namespaces (#2022).
- Search and embeddings. ONNX embeddings (#2), and code search that ranks the file that defines a symbol first (#327).
- Corpus Hub corpora. New packs such as vectra-core (#1994) and agent-input-security (#2509).
To every one of you: thank you.
How we got here
From rc.1 to today in eight steps. Each one links to the post that told it at the time, with the losses left in.
rc.1: one Rust binary that speaks Elasticsearch
The first release candidate passed 1,326 of 1,329 Elasticsearch conformance cases, and its changelog named the 3 it missed. Today it passes 1,444 of 1,454. Read the rc.1 changelog
We broke rerank, then fixed it in public
Our rerank stage shipped scoring 0.3822 nDCG@10 while plain BM25 scored 0.7750. One request shape was wrong. Fixed, it scored 0.8299, and the loss stayed in the post. Does XERJ beat Jev?
28% off the index
We dissected real segment files before writing any Rust. Three of the four format changes ended up different from the plan, and the test index went from about 5.52 MB to 3.99 MB. Cutting the index 28%
The rc.80 gates
Each feature got a bar, written down before the work. Three gates passed, three failed and one split. The failures became issues #1091 to #1094. The rc.80 gates
Corpus Hub
A public registry of corpora for agents: each source pinned to a commit, its licence reviewed, its pack signed. It launched with four corpora and had 100 live by October 6. The Corpus Hub
Corpus Hub v2
Ask a plain question, and the CLI picks the one signed pack that answers it. It pulls 4.4 MB and answers on your machine: 1.7 to 2.3 seconds the first time, 37 to 57 ms after that. Corpus Hub v2
rc.99: autoindex that respects your laptop
Autoindex became resource-aware, so a laptop stays usable while it indexes. Agents can ask up to 50 questions in one call, each with cited evidence or a clear miss. 116 merged changes, 20 community members. rc.99
Your field reports made autoindex faster
A compression change in rc.78 made autoindex about five times slower. Field reports found it, and the merge fix landed about seven hours after the 5 GB reproduction. On the 1 GB gate corpus, the index now takes 1.80 bytes per source byte, down from 3.50. How your field reports made XERJ autoindex faster
The pattern is the same each time: measure, publish what failed, and fix it, often with a report from one of you.
12,000 stars in 12 days
Between rc.1 on July 8 and rc.100 on October 27, we shipped about one release candidate a day. Many fixes in them started as a field report from a person or an agent that used XERJ on real work.
A new way for AI to reach data
XERJ is one Rust binary that indexes your code, docs, specs and logs, adds packs from the Corpus Hub, and gives your agent cited answers.
Agents today mostly find data the slow way. They grep, open a file, read it, and grep again. Each loop costs tokens and time. XERJ gives them a search engine to ask instead.
Memory that always works for you, local and remote
SHIPPINGLocal. xerj autoindex turns a folder of code, docs, specs and logs into an index on your machine. Your agent can also store facts with POST /_memory/{namespace} and recall them later by meaning or keyword. Each namespace is its own index, so agents do not read each other's memories.
Remote. The Corpus Hub holds pre-indexed packs of public knowledge. Ask a question with xerj ask. XERJ picks the one pack that answers it from a signed catalog, downloads it, and answers on your machine. The Corpus Hub v2 post shows how.
What you get. The default embedder is lexical and runs offline with no API key. Your memory stays on your machine and keeps working when the network does not.
Reference memory for coding agents
SHIPPINGYour coding agent clones and indexes the open-source repositories closest to your task, then searches how they solved the problem. It reads the passage it needs, with its file and line, in place of whole files.
What you get. In our reference coding case study, agents finished the same tasks with 2.7x fewer output tokens at the same 16 of 16 solve rate.
Code, docs, logs and data in one place
SHIPPINGAutoindex reads 36 programming languages with symbols and line numbers, plus CSV, JSON, YAML, SQLite, PDF, DOCX, HTML, email and log files. Search is BM25, vector kNN, or both together. XERJ speaks the Elasticsearch API, so the clients you have already connect. The Elasticsearch scorecard shows where it wins and where it loses.
In the official MCP Registry
SHIPPINGxerj mcp gives your agent 23 tools: search, code search, go to definition, agent memory, and Corpus Hub search and ask. XERJ is listed in the official MCP Registry as io.github.xerj-org/xerj. One command, xerj init, connects it to Claude Code or Cursor. See XERJ for agents.
The road to 1.0
The goal for 1.0 is simple: every public claim checked against the release binary, the way we ran the rc.80 gates, and every input either honoured or refused clearly. These items are on the roadmap for it:
- An MCP server for the Corpus Hub, so agents can query packs without cloning their sources (#1785).
- Calibrated confidence on MCP answers, with flags that tell the agent when to hold back or ask a person (#1786).
- Version-pinned answers with file and line citations (#1789).
- Symbol and call-graph queries over MCP (#1791).
- Signed release binaries (#1794).
Before 1.0, we must also fix two open defects. A node can stop when the machine runs out of memory (#1122). Writes do not yet replicate across a multi-node cluster (#1170). Until then, XERJ runs as a single node by default, and we do not claim multi-node production readiness.
Our aim is that every agent can ask a search engine for the data it needs, with a citation, on its own machine. With 100 contributors, we are closer to that than we were in July.
Give your agent a search engine
Install XERJ (docs: https://xerj.org/llms.txt), index this project's sources, and set up reference coding: clone and index the open-source repos closest to what we're building, and search how they solved a problem before writing code.
Then tell us how it went. A short field report is how you join: what you indexed, what you used it for, and your honest verdict.
- Join the community, the field report
- Contributing
- Corpus Hub
- Discord
- X
Read more from the blog: